Private AI

Nano GPT logo
NanoGPT
Nano GPT logo
NanoGPT
Nano GPT logo
NanoGPT
Search


All conversations

Create

Chat
Studio

Explore

Models
Pricing
AI Apps
Blog

Library

Gallery
Workspace
Usage
API
Suggestions and bugs
Use cases

|

Terms

|

Privacy

|

Refunds
Balance
Subscription
Teams
Referrals
Presets
Settings
FAQPress & mediaBrand assetsBenchmarksEarn crypto
  1. Models
  2. Text
  3. Moondream

Moondream 3 Preview

Moondream 3 Preview is the original 9B mixture-of-experts vision-language checkpoint with 2B active parameters, for visual question answering, captioning, OCR, and visual reasoning. It accepts text or one image with optional reasoning, a 32,000-token context, and up to 4,096 output tokens.

  • Reasoning
  • Vision

Added Oct 16, 2026

Model weights

Pricing

Auto routing · per 1M tokens
Input
$0.30
Output
$2.50
Compare provider prices

Specifications

Context window
32K
Max output
4.1K
Parameters
9B / 2B
Total / active

Image examples

Download an image and attach it in chat with the sample prompt. Each example uses one image.

Caption a scene
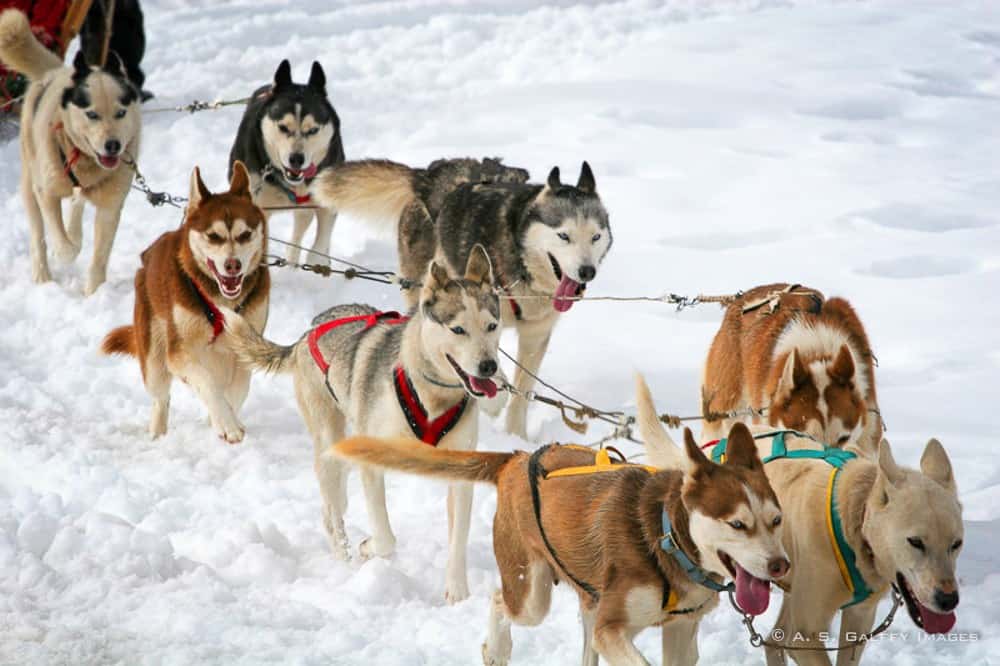
A team of sled dogs wearing harnesses and running through snow.

Sample prompt

Describe what is happening in this image. Include the animals, their equipment, and the setting.
Download imageMoondream release notes · Photo: A.S.L./Getty Images

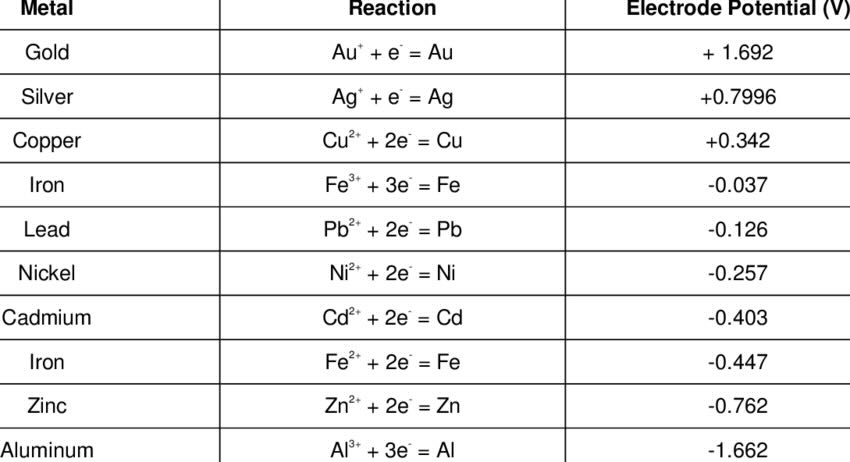
Read and compare a table

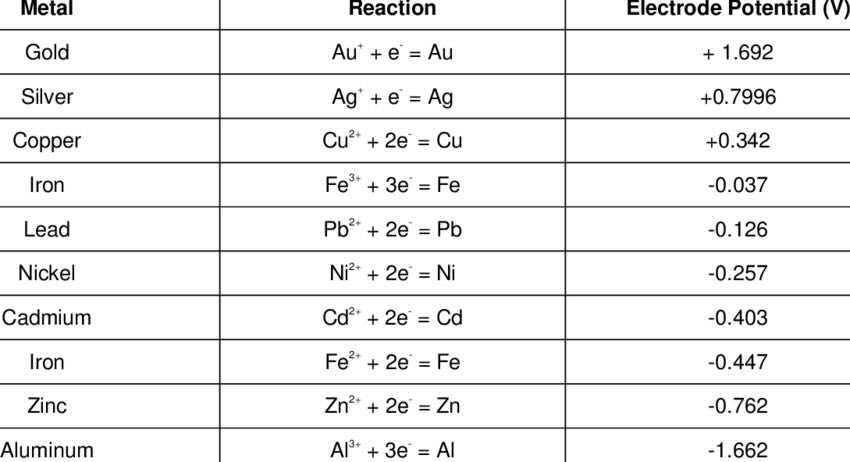
A table of metals, reduction reactions, and electrode potentials in volts.

Sample prompt

Read the electrode-potential table. List the metals with positive potentials and their values, from highest to lowest. Preserve the signs and units.
Download imageMoondream 3 Preview release notes

Benchmarks

No public benchmark scores for this model yet.

Providers

Loading provider options…

Related text models

Compare Moondream 3 Preview with similar models from the same provider or model family.

Moondream 3.1 9B A2B

moondream/moondream3.1-9b-a2b

Moondream 3.1 is the successor to Moondream 3 Preview: a distinct 9B mixture-of-experts vision-language checkpoint with 2B active parameters, for visual question answering, captioning, OCR, and visual reasoning. It accepts text or one image with optional reasoning, a 32,000-token context, and up to 4,096 output tokens.

OrcaCyber K3.1 Pro Uncensored

orca/orcacyber-k3.1-pro

An abliterated / uncensored variant of Kimi K3.1 Pro for authorized security research, coding, and tool use. Accepts text and images, with reasoning enabled by default and an option to turn it off. Supports a 1M-token context window, up to 943K output tokens, tool calling, and structured output. Offensive work is permitted only within an authorized security engagement.

Ripple 65B Preview

ricursiveai/ripple-65b-preview

Ripple 65B Preview is Ricursive Intelligence's Apache 2.0-licensed, 65-billion-parameter reasoning model for coding and agentic tasks. It accepts and returns text, supports automatic tool calling and JSON output, and has a 16,384-token context window shared by input and output. It reasons before answering by default, and this preview's thinking cannot be reliably turned off.

Tencent Hy4

tencent/hy4

Tencent Hy4 accepts text and images and returns text, with a 1,048,576-token context window and up to 65,536 output tokens. It supports coding, long-document analysis, automatic tool calling and structured output. Reasoning is enabled by default at high effort; choose low effort or turn reasoning off.

Assistant Pepe 32B

sicariussicariistuff/assistant-pepe-32b

Assistant Pepe 32B is SicariusSicariiStuff's Qwen3-32B finetune for creative writing, brainstorming, roleplay and irreverent conversation. Trained on UBW Tapestries, it has a built-in conversational persona and replies without a separate thinking mode. It accepts and returns text, with a 40,960-token context window and up to 8,192 output tokens.

OrcaCyber MiniMax M3.1 Flash Uncensored

orca/orcacyber-minimax-m3.1-flash

An abliterated / uncensored variant of MiniMax M3.1 Flash for authorized security research, coding, and tool use. Reasoning is always enabled, with selectable effort. Supports a 262K-token context window, up to 131K output tokens, tool calling, and structured output. Accepts text input. Offensive work is permitted only within an authorized security engagement.